
AI Native SaaS
Trust & safety
P0
AI Detector that users could Trust, not just Try.
End-to-end design of QuillBot's free, sentence-level AI Detector that resided at an intersection of model uncertainty, user anxiety, and business growth.
500K+
#2
#200
90%↓
Executive Summary
Turning a high-intent search opportunity into a free AI Detector that writers could use confidently.
Situation
The increasing interest in AI detectors, witnessed through soaring search volumes, created an opportunity to support writers at a key moment.
Task
Design a useful & credible free AI Detector while paving the way to relevant writing tools QuillBot is known for.
Action
Led end-to-end design, from data & UXR insights through strategy, prototyping, UI, with stakeholder alignment, dev-handoff, and iterating from live product signals.
Results
500K+ WAU in week twelve, #2 organic ranking, higher conversion, and a reduced feedback burden after recalibration.
My role
Product Designer (P0)
Core team
PM, 2 engineers, copy writer, AI research, and business
Market
Global · English, German, Spanish, French
My contributions
I owned, influenced, and delivered.
What I directly owned
Product strategy, design exploration, experience principles, design system contribution, prioritisation rationale, executive storytelling, developer handoff, and quality analysis.
What I influenced
Product roadmap, design system, leadership decisions, and team alignment in a cross-functional setting across the globe.
What partner teams delivered
Engineering implementation, analytics instrumentation, product copy, product illustrations, AI models, Product management, and dedicated QA post launch.
FINAL DESIGNS
Light mode · mobile

Dark mode · mobile

Light mode · desktop
👉🏾
Case study in one sentence
Instead of just showing a score, I focused on helping users understand what the result meant and used their feedback to improve the product.
02 The challenge
The tool could be fast, but judgement could never be absolute.
Writers scan text for AI with an emotionally loaded question: “Will this text be judged as mine?” A fast, definitive-looking result can attract clicks while creating real harm when the model is wrong.
🚀 1.5M MAU
The AI Detector product challenge was to achieve 1.5M MAU driven by organic search in Tier-1 countries.
“The score looks certain”
Providing a score is generally interpreted to be certain. The challenge was to protect customer's trust by necessary education about model uncertainties.
We needed a fast, free, SEO-friendly, and un-opinionated tool that gave users clear results without overstating their accuracy.
The organisational tension
WHY IT MATTERED
Acquisition
Search volume for AI Detector was soaring, which the competitors were already monetising.
Unfair evaluation
Most users were flagged 100% AI for texts that they wrote themselves but modified using AI, leading to unfair evaluation.
A complete portfolio
QuillBot had all writing tools that a user needs after AI-Detection, without feeling like a hidden lead-generation gate.
CHALLENGES
Model
Like any AI Detection model, QuillBot's model too was probabilistic with fluctuating accuracy based on text length, language, and type.
UX
A non-technical writer should be able to understand the results in seconds, in both mobile & desktop, for both light & dark mode.
Business
Like a loss-leader, AI Detector despite being free to use, should be able to cross-sell hero products with higher conversion potential.
Legal
Product recommendations had constraints around direct paraphrasing in the detector flow.
🔍
Design question
How might we give writers evidence to act on?
03 What we learned
We shipped an MVP to hear directly from the horse's mouth.
While the MVP witnessed a soaring traffic of ~100K WAU with predictable usage patterns, the feedback channel received tickets related to trusting the score, false positives, specificity in the text, and how to improve the score. In a nutshell, every signal in the user journey was primarily about trust.

We tested the waters before diving · We launched an MVP on 4th Jan 2024 · ~100K WAU
01 · Search behaviour
AI Detector demand was rising sharply, which opened the door to think of it as a free entry-point product leading users to writing vertical after AI scan.
02 · Competition
Other AI Detectors were heavily gated, overly judgemental, cluttered, and provided a black-box score without much explanation.
03 · Writing context
Dark mode in desktop was meaningful to academicians burning the midnight oil; while ~40% mobile usage showed context switching while working.
04 · Model boundry
On-going efforts of a classification model tuning for AI detection made a feedback loop non-negotiable.
01
TRUST
A score alone produces anxiety, not understanding.
Users sought score explanation, where did it come from. They also needed clear take-aways as a report evidence.
02
BEHAVIOUR
User arrive here to evaluate & fix their text not receive a score.
Users arrive to evaluate text, after which they need a credible path to revise, improve, or continue working.
03
QUALITY
Feedback is a non-negotiable product infrastructure.
Upfront feedback infrastructure is a strong product move to improve the experience, and train the model for accuracy.
THE OBVIOUS MOVE
Design a detector score and optimise conversion.
MY REFRAME
“Explain the result clearly and suggest the right next step."
This turned the tool into an experience that helps users understand results and improve their writing.
04 Design approach
Starting with clear product principles
In collaboration with product manager & team, I defined a few product considerations to keep the experience consistent through launch and future improvements.
01 · SOFT LABEL
Soft labelling, not verdict.
Use probability language "likely" to avoid being certain, and explain result types.
02 · LOSS-LEADER
Free, no-login first use.
High SEO volume to be provided value without being gated, as a loss leader.
03 · SPECIFICITY
Sentence level specificity
Sentence level highlights instead of highlighting entire text to be more specific.
04 · CONTEXTUAL
Next right tool after detection
Cross-sell relevant QuillBot writing tools after AI Detection to provide value.
05 · FEEDBACK
Feedback without friction
Retain feedback infra in its most accessible position to keep the learning loop on.
06 · IN-PLACE EDITS
Manual intervention
Make an edit, rescan, compare the result, and repeat without leaving the detector.
I used this framework as the decision filter for every concept.
VALIDATING THE PRODUCT PRINCIPLES
A signal from competition benchmarking.
FEATURES
Copyleaks
Grammarly
Sapling
GPTZero
Originality
Free to use
Un-opinionated
Soft verdict
Score explanation
Easy feedback
Sentence highlight
Multi-language
Writing tools
Manual edits
Discoverability
Export text
Download report
Prevent model abuse
Clarity & visibility
7/10
5/10
9/10
9/10
User control
6/10
6/10
7/10
5/10
Trust-worthiness
5/10
7/10
8/10
7/10
9/10
End-goal success
4/10
8/10
5/10
3/10
4/10
Scan speed
2/10
4/10
7/10
8/10
9/10
Contextual next
3/10
5/10
7/10
6/10
3/10
Non-negotiable product requirements
Should have
Good to have
IDEATION
Messy drawing board, clear direction.
Design began with sketching ideas that considered non-negotiable requirements as the base, followed by optimising the design for user satisfaction.

Four concepts. One ultimate goal
I scored the ideas with product and leadership on score clarity, control, trust, actionability, mental model & coherence with other QuillBot products.
CONCEPT 01 · REJECTED
Side-to-side comparison
Strong user control, but overwhelming, lacking score clarity, and confusing which panel to refer.
Clarity & visibility
User control
Trust-worthiness
Actionability
VERY HIGH
Mental model
COMPLEX
Product coherence


CONCEPT 02 · REJECTED
Emulating Google Doc comments
It has strong actionability at surgical level, but lacks product coherence, and clear explanation on the score.
Clarity & visibility
User control
Trust-worthiness
Actionability
HIGH
Mental model
MODERATE
Product coherence
CONCEPT 03 · REJECTED
Classification at individual level
Classifying each sentence into four categories adds unnecessary complications to the mental model.
Clarity & visibility
User control
Trust-worthiness
Actionability
MEDIUM
Mental model
COMPLEX
Product coherence


CONCEPT 04 · SELECTED
Spend time with the score first, then edit
Classifying & colouring the overall score enhances legibility & consistency with sentence level highlights.
Clarity & visibility
User control
Trust-worthiness
Actionability
LOW
Mental model
SIMPLE
Product coherence
👉🏾
My recommendation
Double down on concept 04 by improving actionability & control, and without compromising trust, clarity & simplified mental model.
Experience that was incrementally introduced.
We shipped the first complete version (V1) on 8th Feb, 2024 to seek user feedback on score clarity, sentence highlights & false positives.
NOW
Use a liberal AI detection model, legible classification, and score explanation.
NEXT
Add multi-language, sample text, and leave bandwidth for necessary course correction.
LATER
Merge AI & Plagiarism Detection into a unified editor.

We launched V1 on 8th Feb 2024, after 5 weeks of MVP launch · gathered feedback & monitored data
ELEMENTS OF V1 LAUNCH
01 · ICON DESIGN
Started by adding the product to the side navigation with a distinct, semantic, and coherent icon design.
02 · SCORE CLARITY
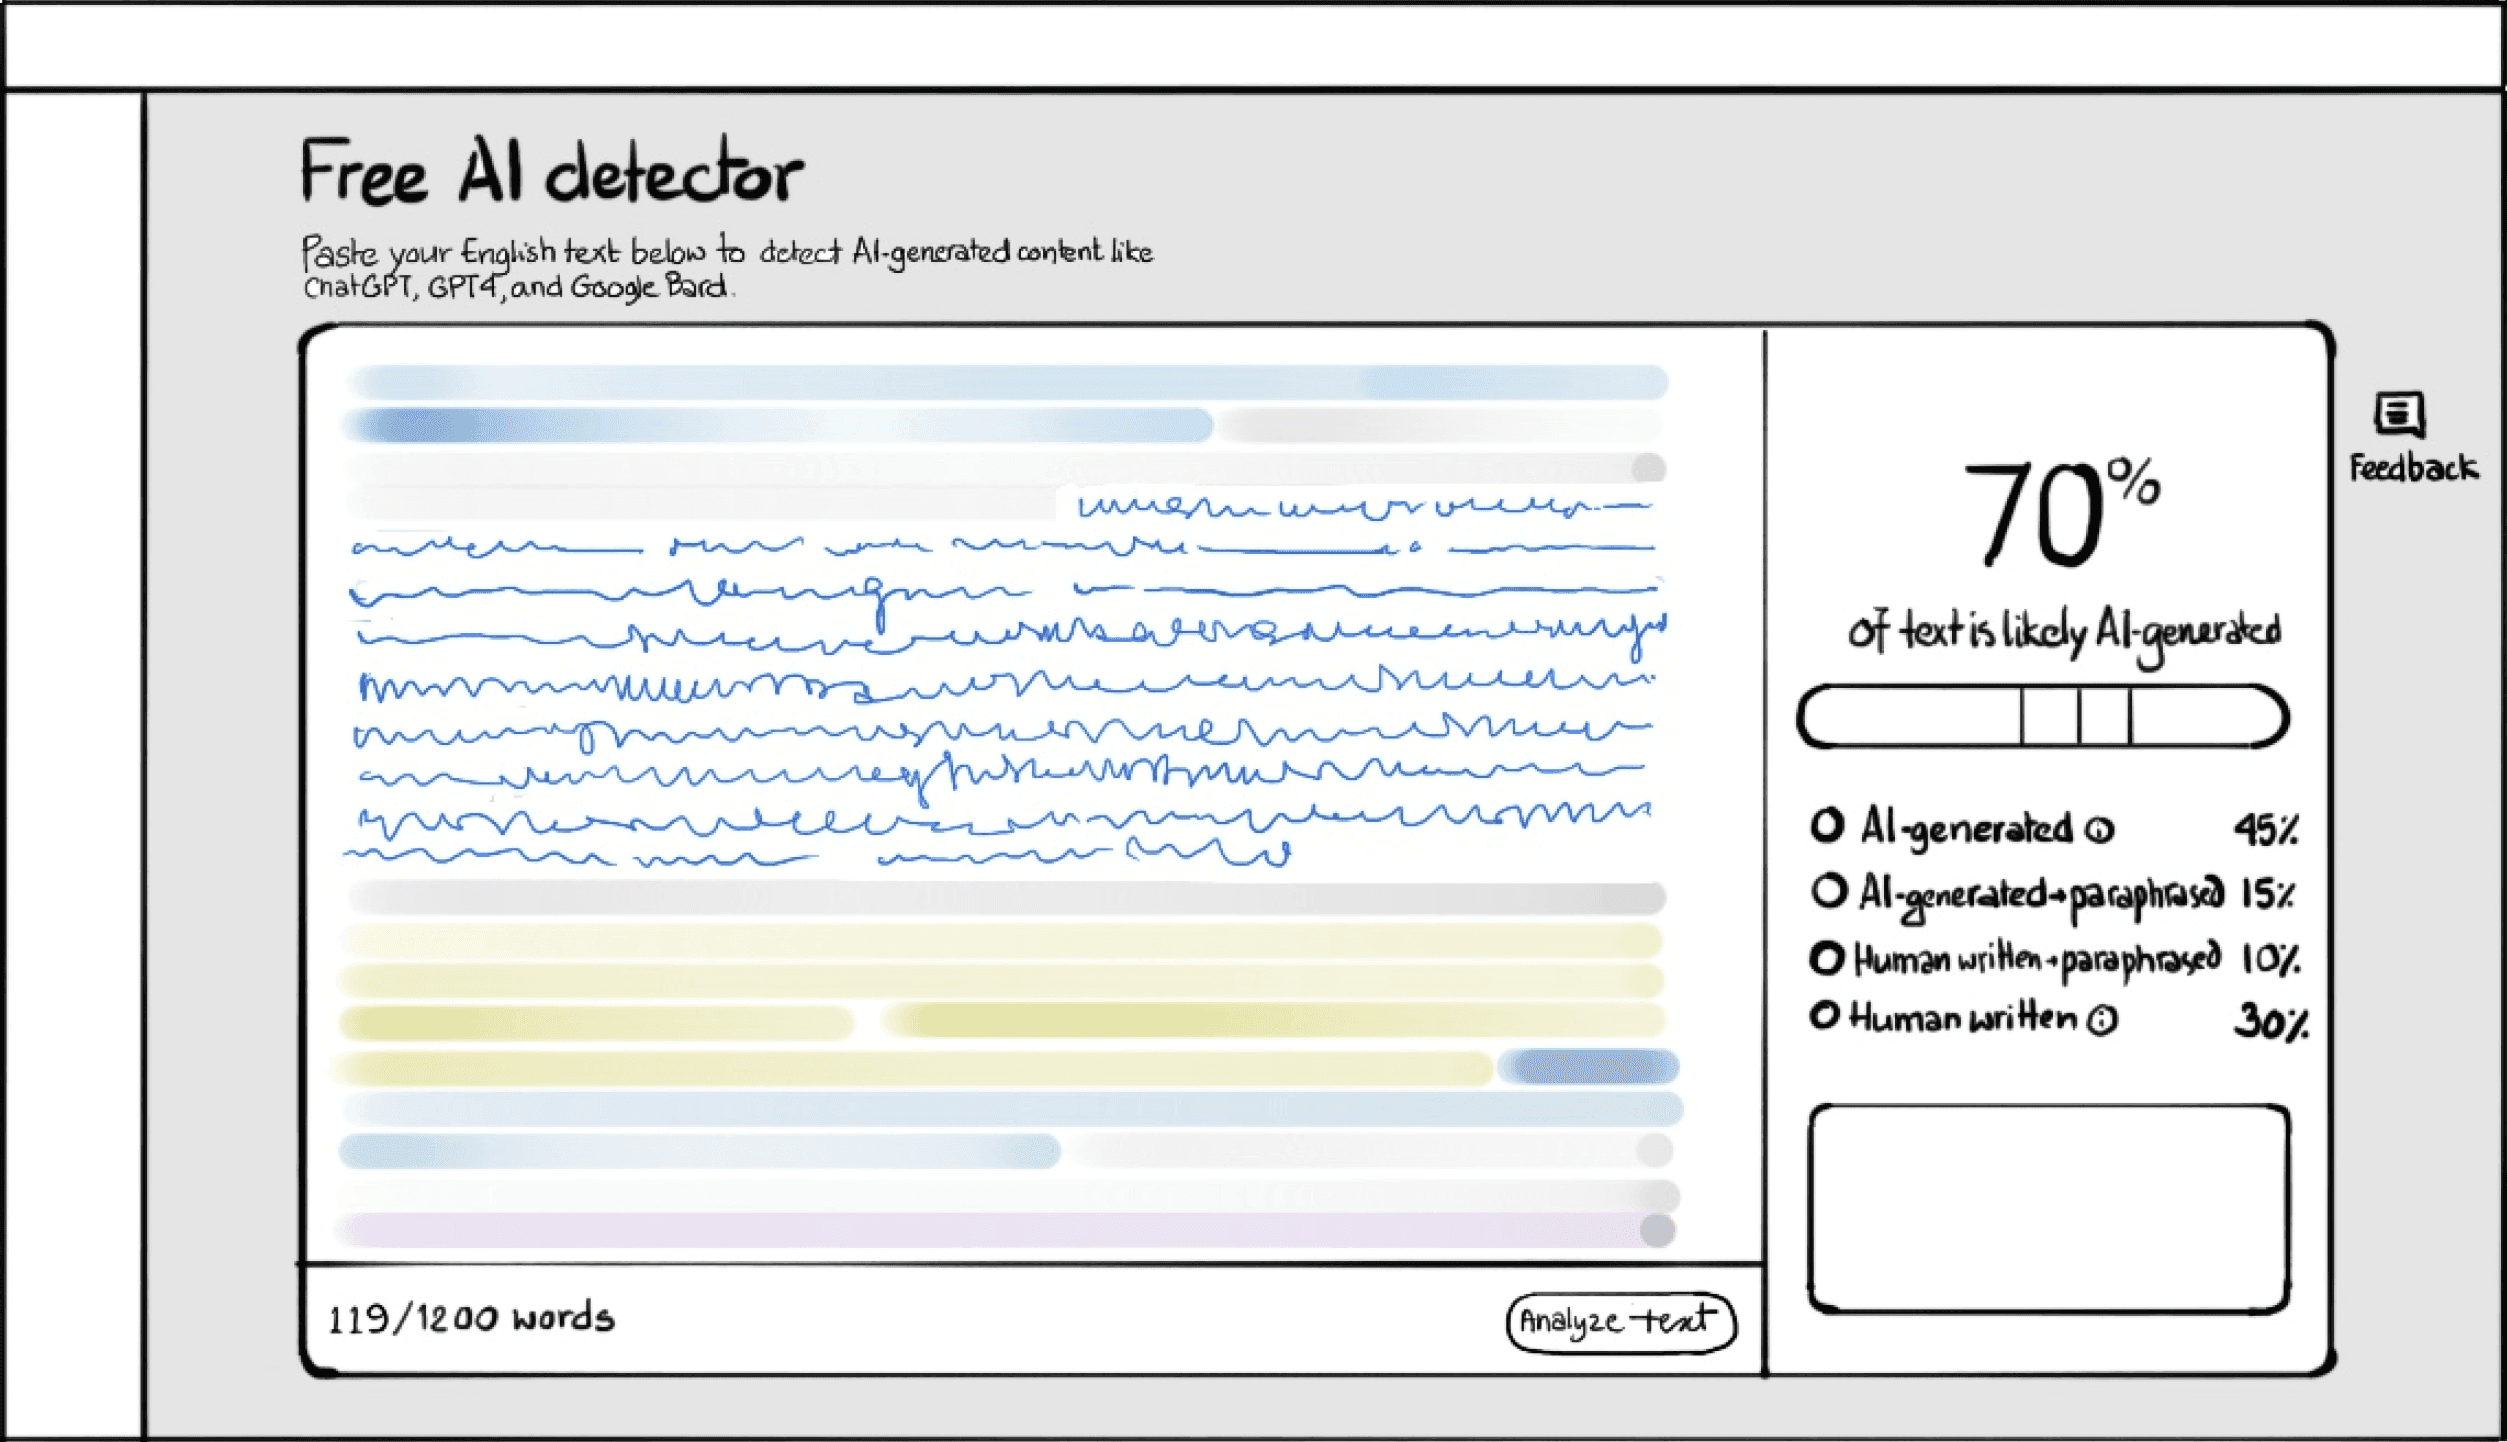
Score clarity was improved by adding sentence specificity, MECE 4-way classification, and colour coded gauge.
03 · ACTIONABILITY
Next action after AI detection is decided to be manual instead of a once-click humanise efforts to avoid brand-risk.
01 · ICON DESIGN
Four icons. One explicit trade-off.
With strong traction and acquisition potential, leadership approved adding AI Detector to the main side navigation. We started with designing a timeless icon for AI Detector for years to come.
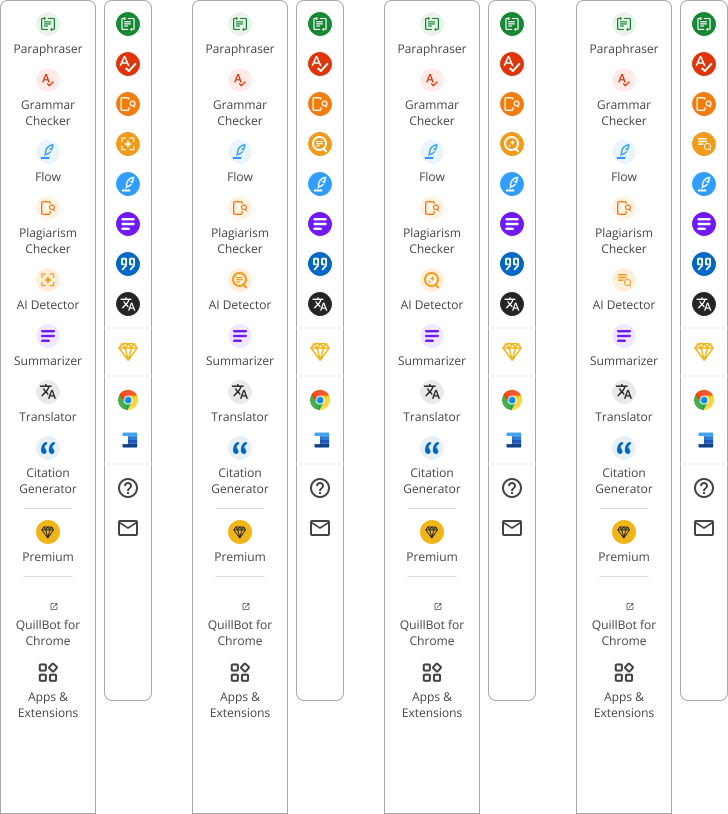
I conducted an ideation workshop with a team of 24 designers to brainstorm on the design of the AI Detector icon, colour code, size, weight, and semantics. We collectively generated 20 designs of which 4 championed based on visual coherence, distinctive look & feel, easy to recognise, and timelessness. Below showcases all the ideas generated by the team.

CLOSER LOOK AT THE DECISION
20 ideas · 4 champions · 1 selected
SHIPPED · V1
Distinct · strong coherence · grows with time

REJECTED
Too obvious · resemblance to search text

REJECTED
Too obvious · goes more with search with AI

REJECTED
Easy to miss · resemblance to plagiarism checker

02 · SCORE CLARITY
Only classification model that exempts assistive writing.
Some competitors had confidence model producing binary results, whereas QuillBot's classification model is capable of measuring amount of text pattern and classify if it is purely AI-generated, Human, Human-written & AI paraphrased, or AI-generated & AI-paraphrased, which none of the competitor was capable of doing.
REJECTED
Not mutually exclusive collectively exhaustive (MECE)

SHIPPED · V1
Focuses on AI-generated text only with MECE framework

MECE framework reduced customer support tickets on false positives.
03 · ACTIONABILITY
What's next after AI detection.
JTBD is to fix text & produce report that can be used as an evidence that the content is free of AI. Extrapolating on this topic, the need to have paraphrasing capabilities was strong. We explored multiple ideas to learn that these ideas are a risk to QuillBot's brand image. Detection & paraphrasing in the same tool is not seen as a comfortable solution to the leadership.
CLOSER LOOK AT THE ALTERNATIVES
OPTION 01 · REJECTED · BRAND RISK
Reusing paraphrasing capabilities on AI Detector after scanning.
a · Default results

b · Rewrite a text portion

c · Rewritten text ready to scan

OPTION 02 · REJECTED · BRAND RISK · HIGH EFFORT
Reusing browser extension capabilities on AI Detector after scanning.
a · Default results

b · Use ext. to rewrite

c · Rewritten text ready to scan


OPTION 03 · REJECTED · BRAND RISK · HIGH EFFORT
Use of the right panel as editor
a · Default results

b · Use ext. to rewrite

c · Rewritten text ready to scan
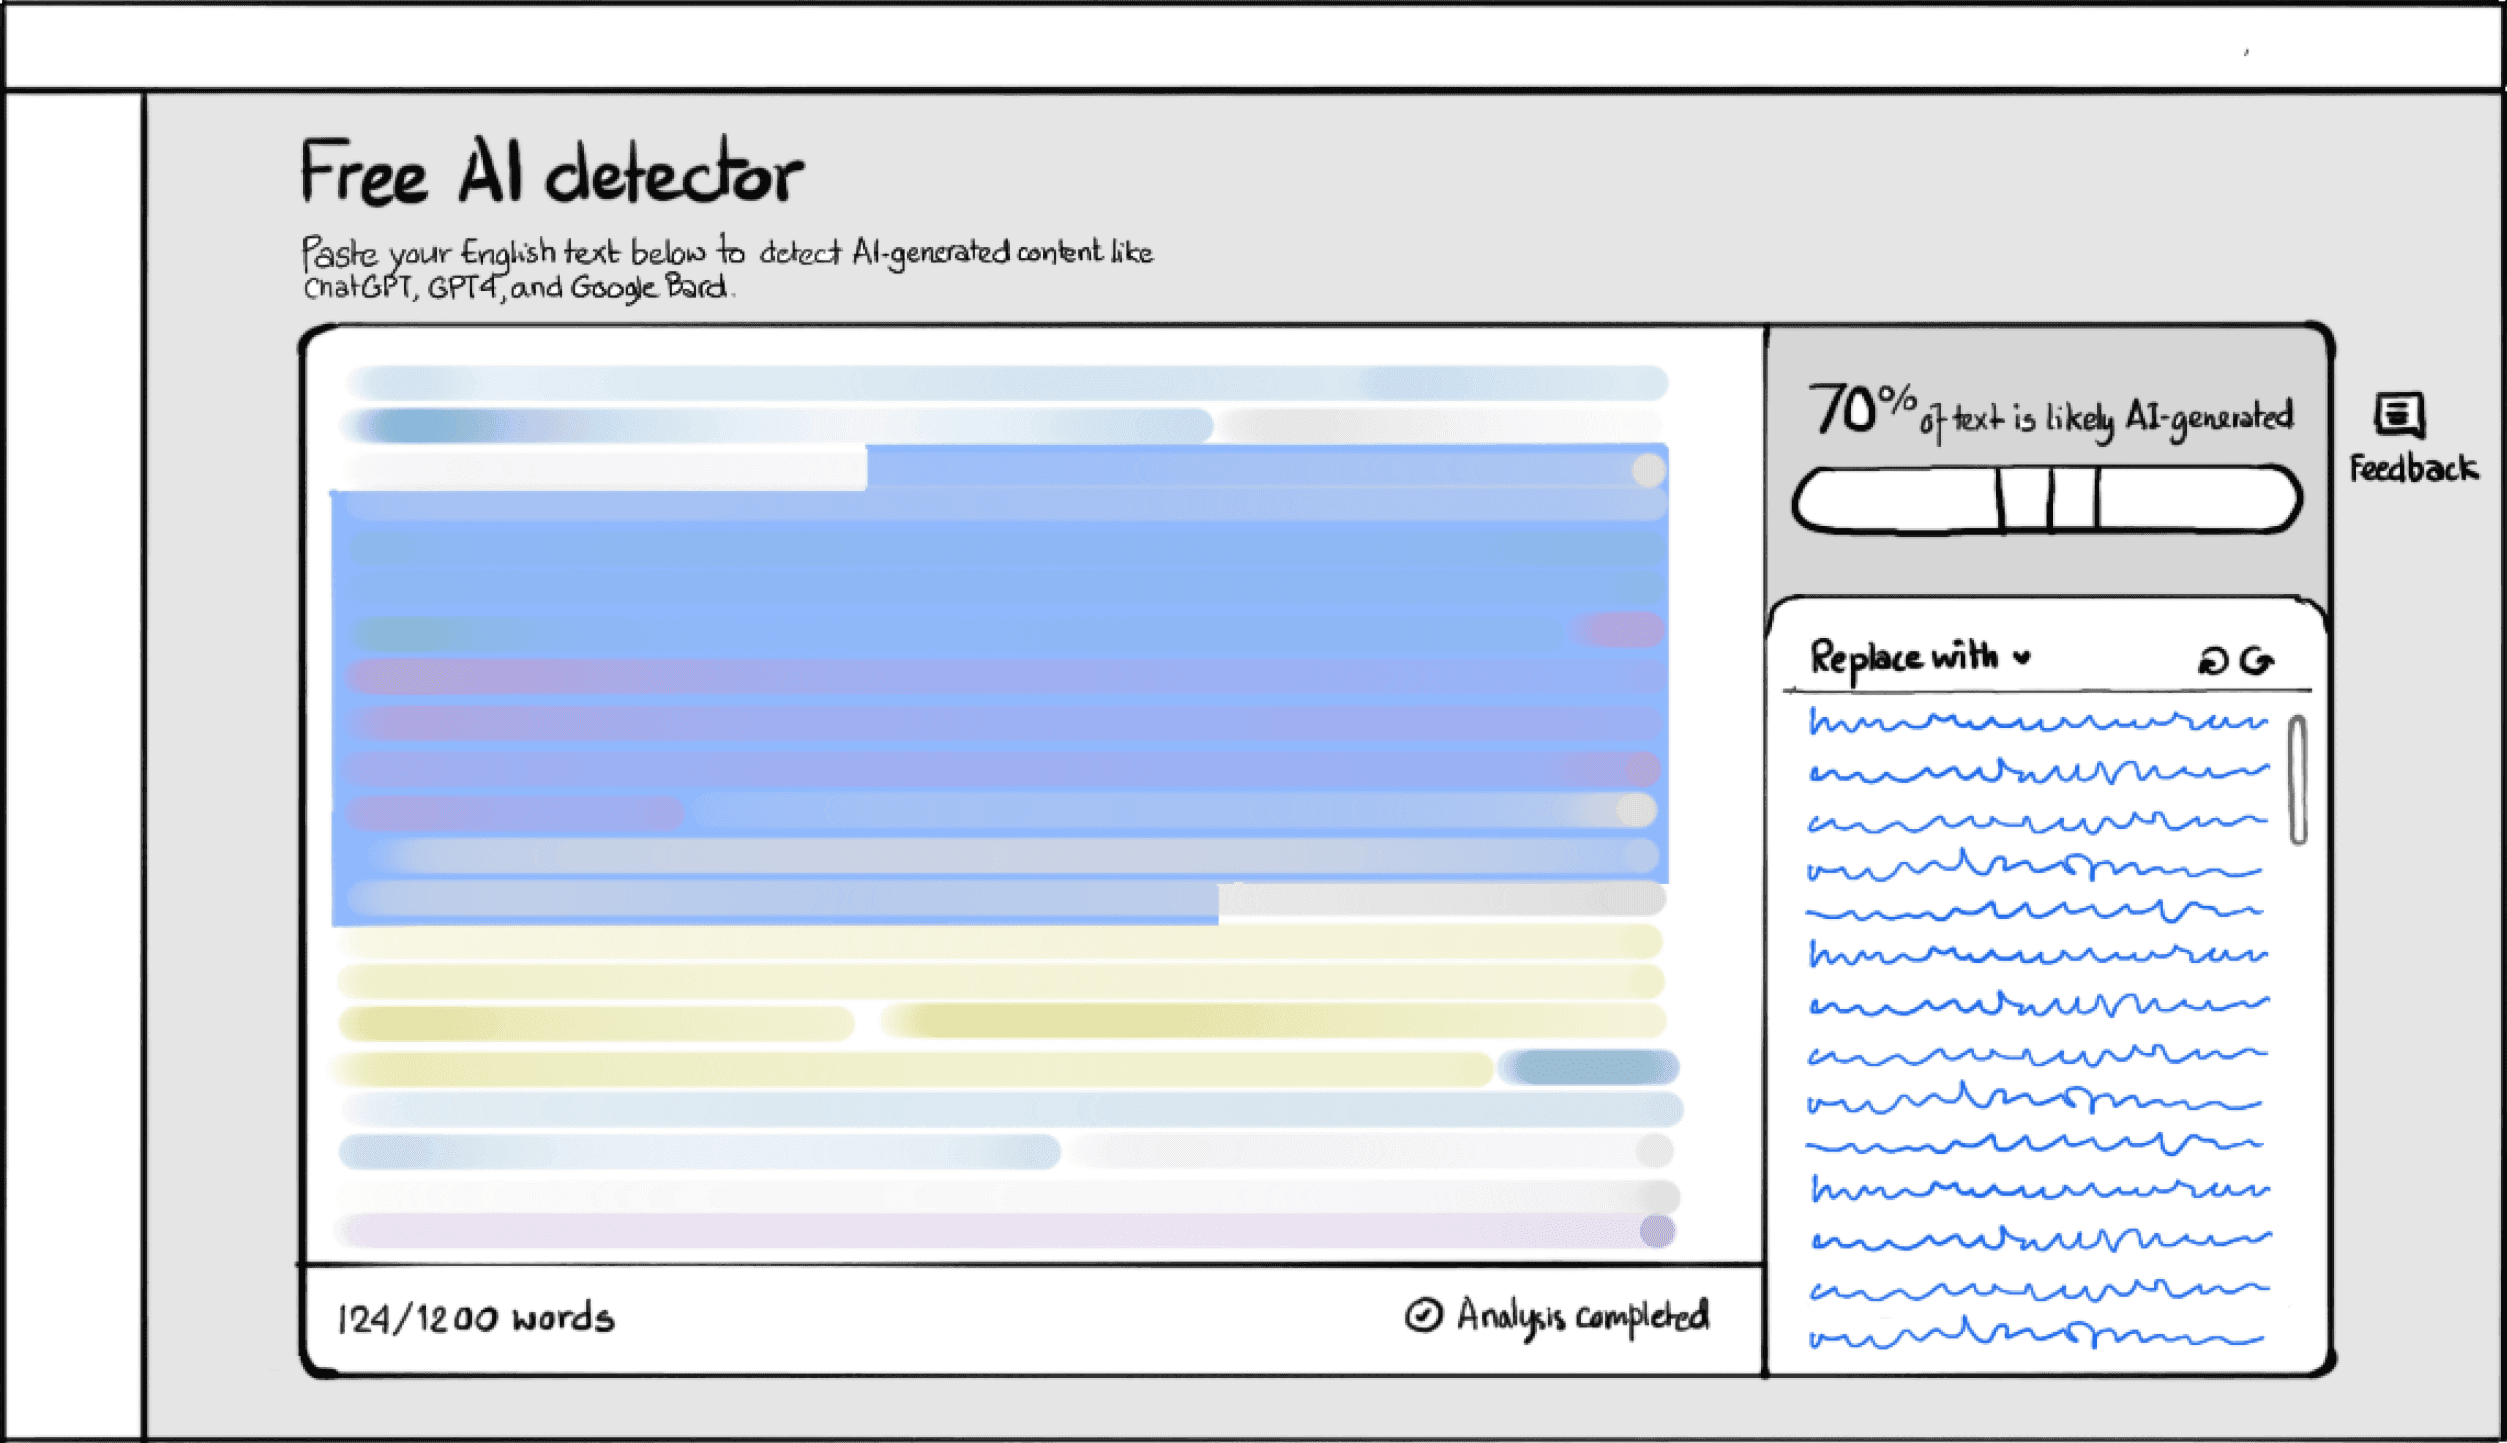

SHIPPED V1 · MANUAL EDITS
User can edit text on AI Detector manually & re-scan.

WHAT SHIPPED IN V1 · 8th FEB 2024
Shipping high bets through ambiguity.
We navigated ambiguity by shipping high bets, followed by monitoring data & support tickets to learn from user behaviour before making updates in the next version.
INTERVENTION
PRIMARY JOB
DELIVERY
All in MVP
Primary action
MVP
Icon to side nav
Discovery
SHIPPED V1
Score clarity
Trust-worthiness
SHIPPED V1
4-way classification
Score explanation
SHIPPED V1
Sentence highlights
Add specificity
SHIPPED V1
Manual edits
Continuity & control
SHIPPED V1
IMPACT · V1
Before · WAU MVP
~100K
After · WAU V1
~300K
LEARNINGS FROM V1
SUPPORT TICKETS
Witnessed higher false positive rate
Support tickets on false positives were among the highest. Users complained that AI detector flagged their self written content as AI-generated.
SUPPORT TICKETS
Demand for In-app AI humaniser
Most users sought for one-click solution to fix their text within the AI Detector, which is unfortunately not aligned with brand guidelines.
SUPPORT TICKETS
Few tickets on tool education
Some users reached out to know more about the 4-way classification, and its impact on the overall score.
BUSINESS ROADMAP
Introduce multi-lingual AI detection
QuillBot's 2024 objective was to go multi-lingual and enter Europe, which led us to prepare the AI Detector for this upcoming challenge.
Pro-active execution of debts.
The defining leadership moment arrived immediately after launch. Feedback showed that the model’s liberal setting was producing too many false positives, turning a model-quality issue into a product-trust event. Translating the learnings into pro-active execution of debts, course correction, and AB experiments.
01 · CONSERVATIVE MODEL
Conservative AI Detection model produced significantly lesser false positives compared to liberal model as per AB testing.
AB test for the two models was independently carried out immediately by product manager & AI team without any design intervention needed. This test revealed that conservative model performed significantly better in reducing false positives, which led to reduction of support tickets.
VARIANT A
Liberal
HIGHER FALSE POSITIVES
VARIANT B
Conservative
LOWER FALSE POSITIVES
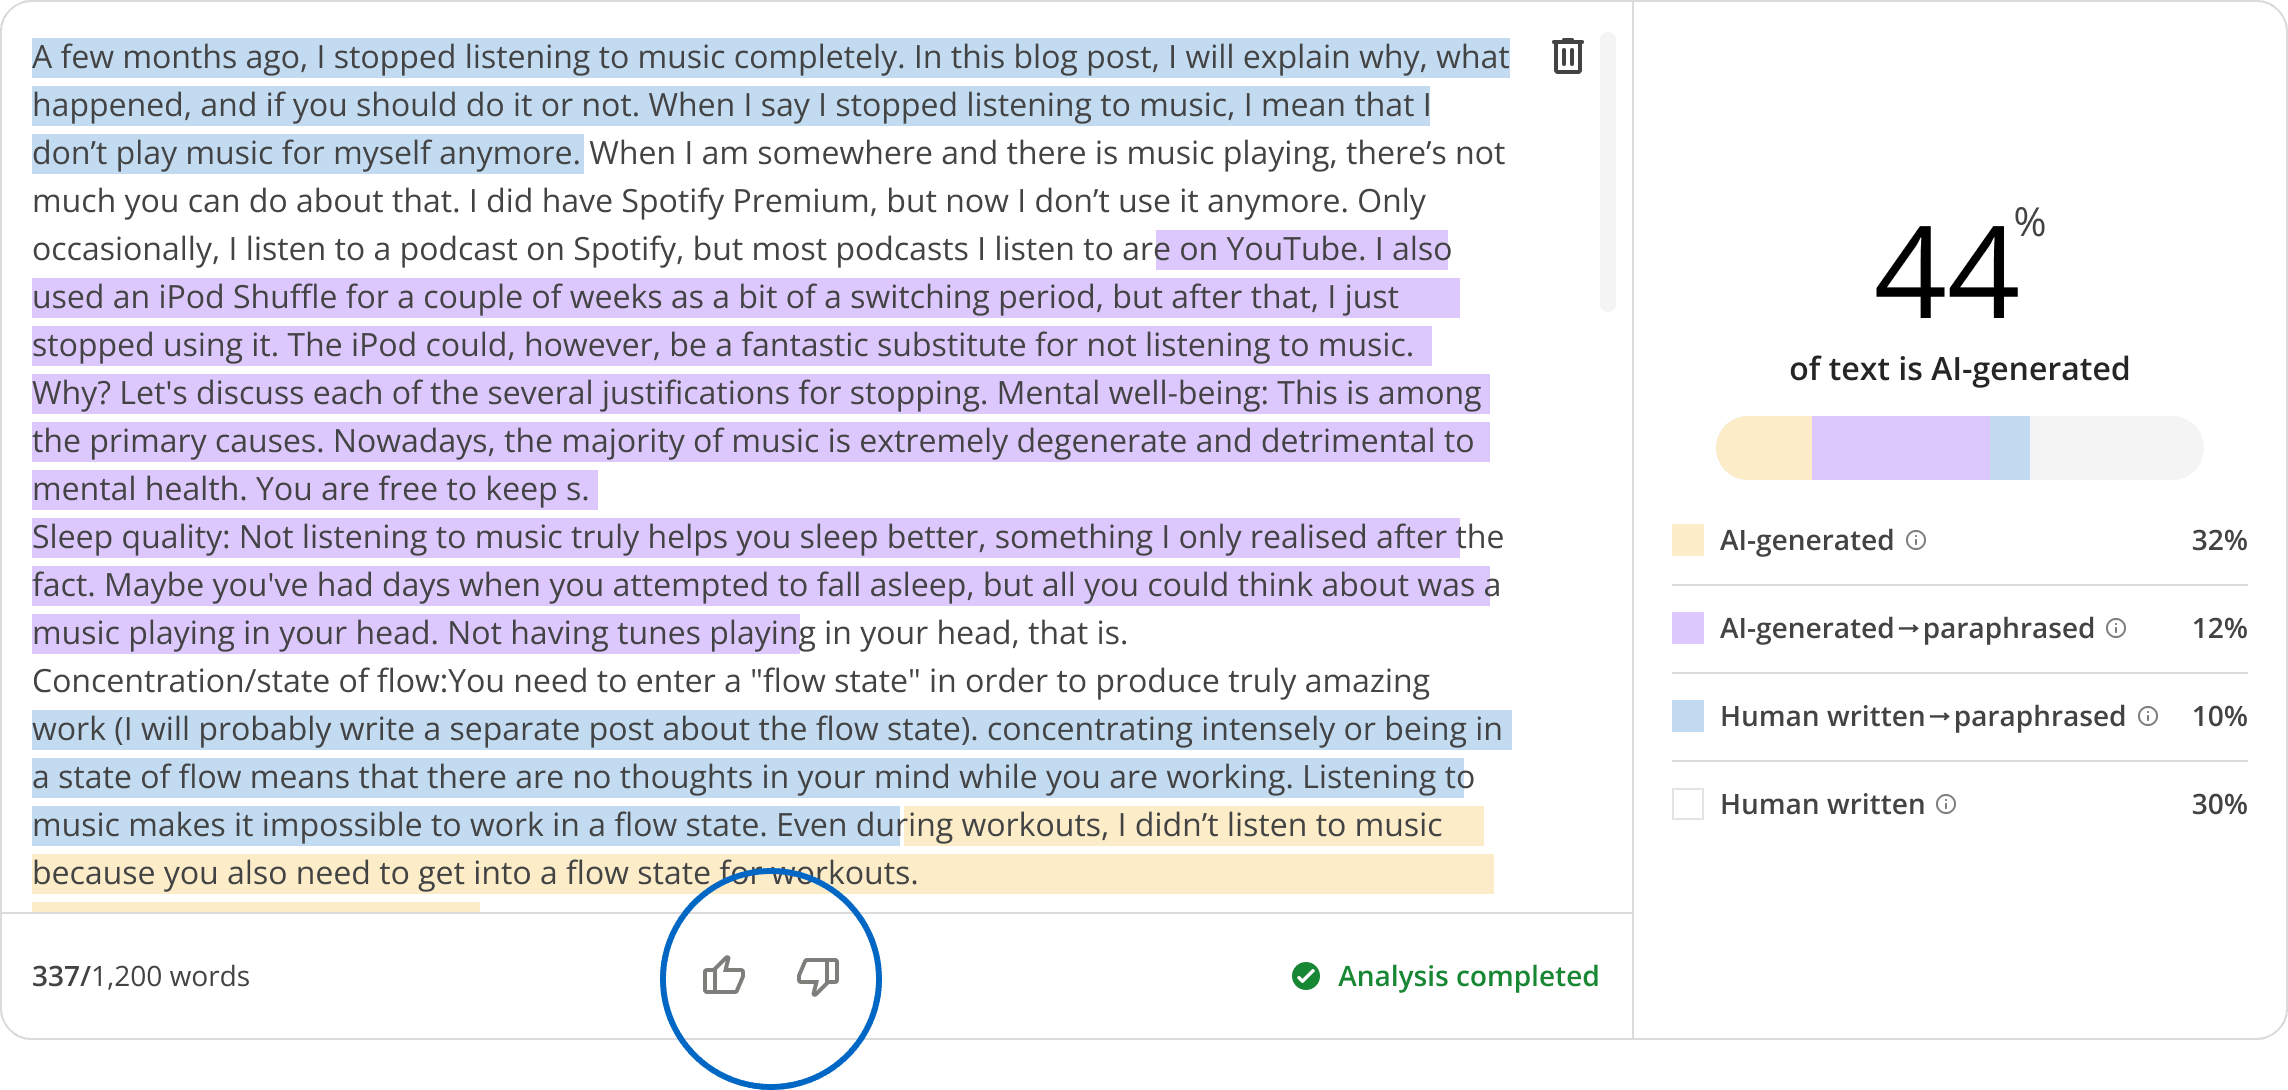
02 · LIKE DISLIKE
Channelise written feedback on false positives to clicking like & dislike with ease.
In discussion with cross-functional team, we arrived at a decision to introduce Like & Dislike button in V2 with an objective to establish a feedback loop infrastructure as a model training data.
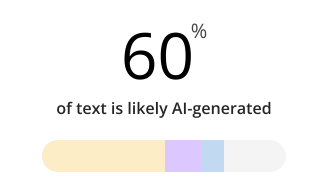
03 · SOFT VERDICT
Moved from certainty to likeliness to set correct expectations for the users.
No AI detector is accurate, hence score certainty sent a wrong message to the users. We softened the verdict in V2 aiming to set correct user expectations that the score should be considered as a soft label followed by human review.
BEFORE

AFTER
04 · CROSS-SELL PORTFOLIO
Paraphraser is highly sought after AI detection compared to Plagiarism or Grammar.
We defined the flow's end with cross-selling premium portfolio products to increase conversion. We launched three variants to test which product gained statistically significantly traction after user detects an AI-generated content.
A · GRAMMAR CHECKER
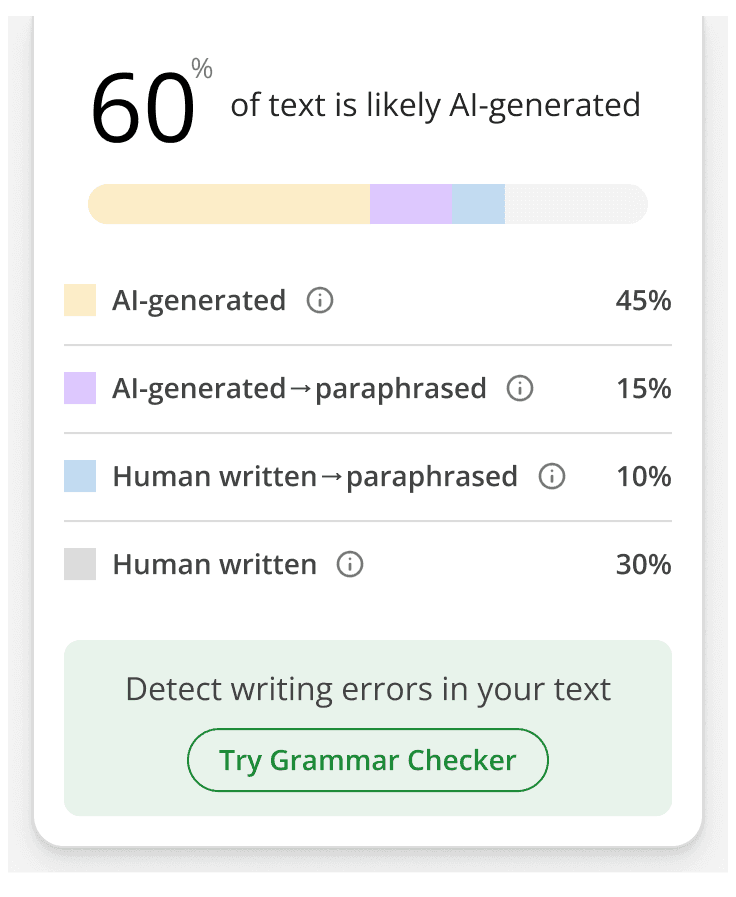
B · PLAGIARISM CHECKER

C · PARAPHRASER · WINNER

05 · MULTI-LANGUAGE
Accommodating Non-English languages to AI Detector was not limited to just four languages.
Based on business strategy to expand in the European region, QuillBot's AI Detector design needed a scalable approach to accommodate multi-lingual capabilities. Language auto-detection, GTM with three languages, and tab layout were the design decisions.

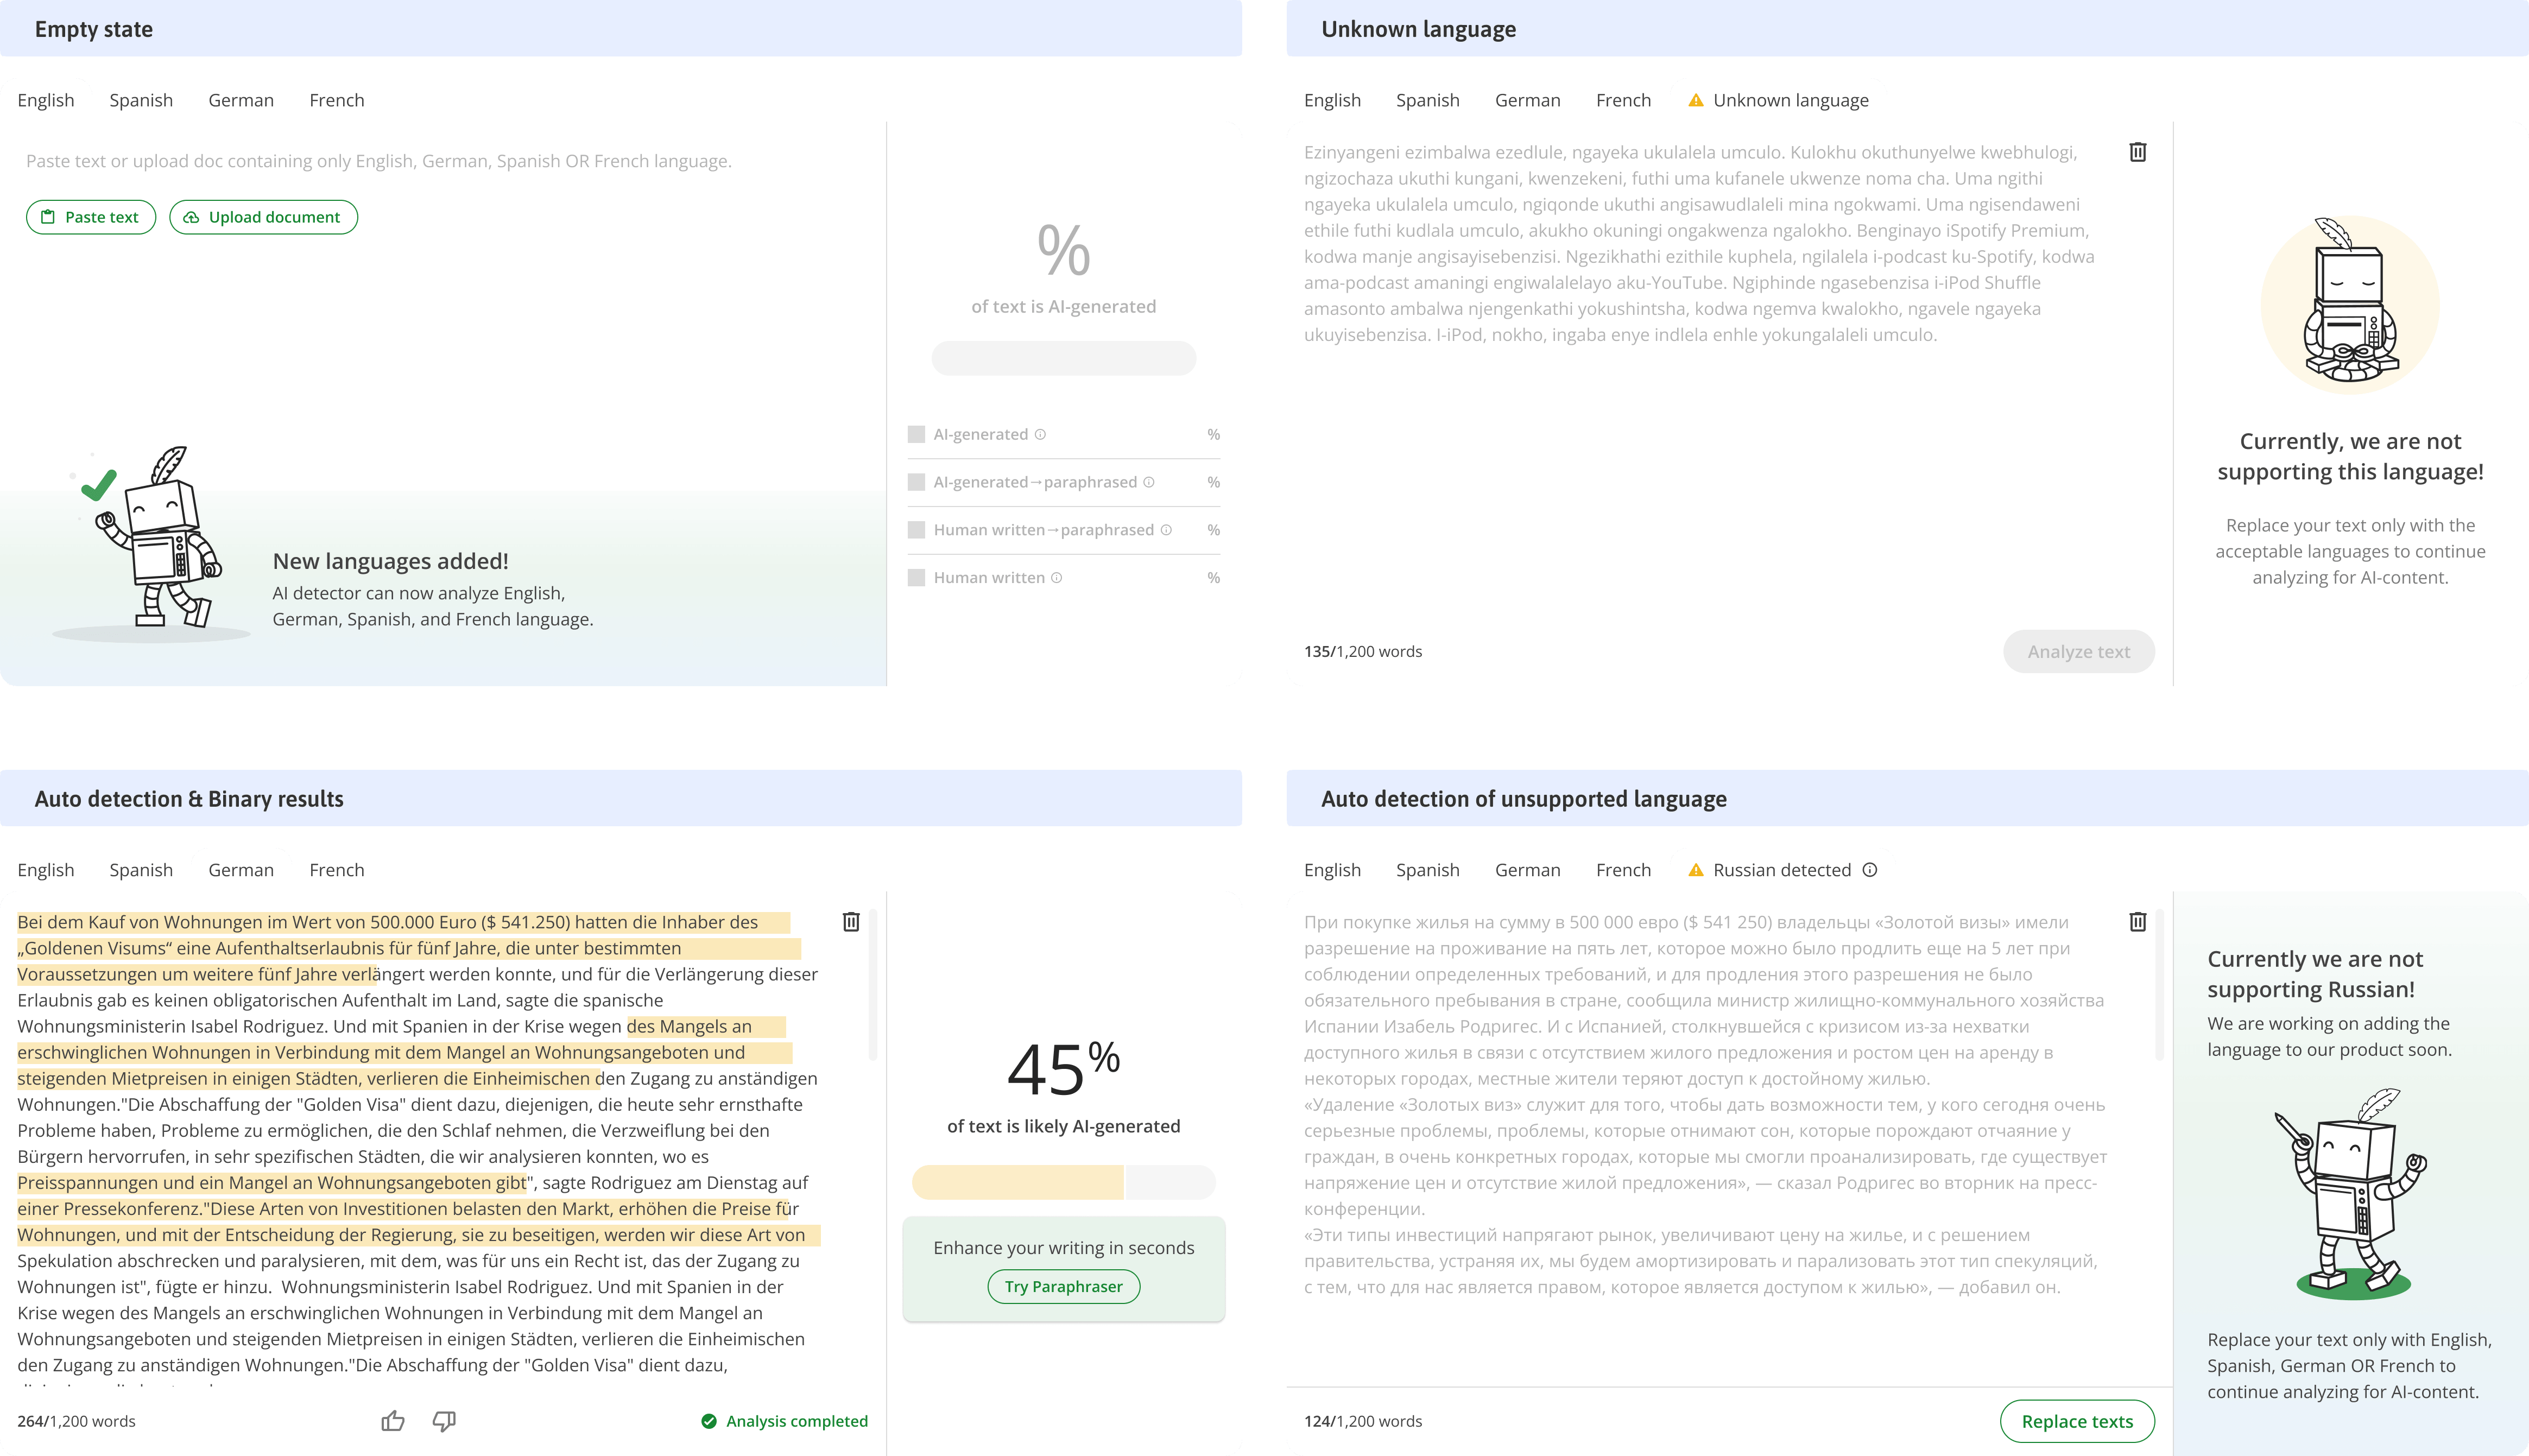
REJECTED · HARD STOP
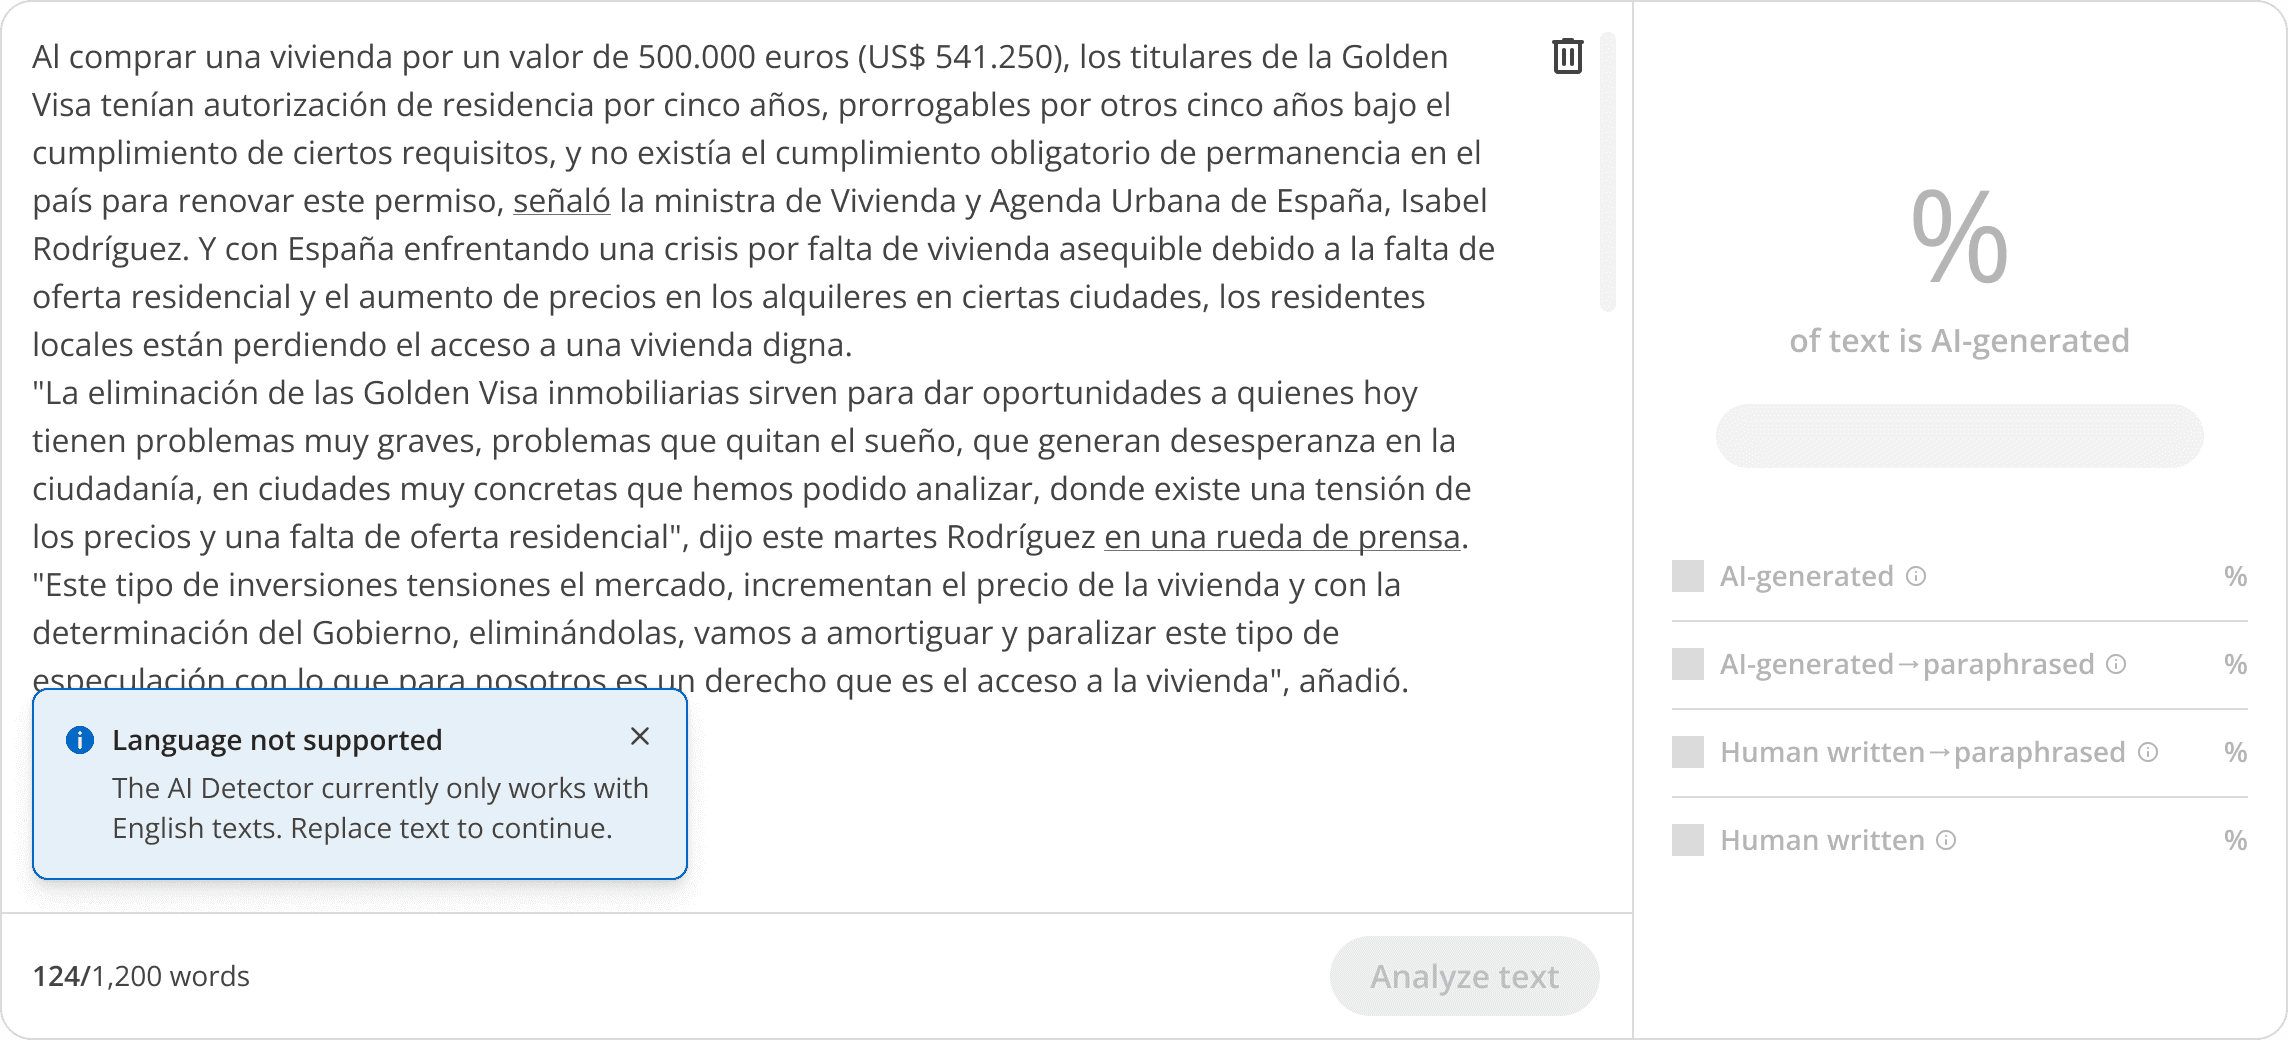
SELECTED · INTUITIVE

06 · SAMPLE TEXT
With an objective of increasing education of the tool's functioning, sample text was introduced.
We switched the AI model from liberal to conservative with an objective to reduce the rate of false positives. In addition to that we added "like" & "dislike" icon buttons to easily provide model feedback, and diverting majority false positive issues from the customer support. We also softened the verdict by phrasing it to "80% likely AI-generated", instead of "80% AI-generated", with an aim to set expectations upfront.
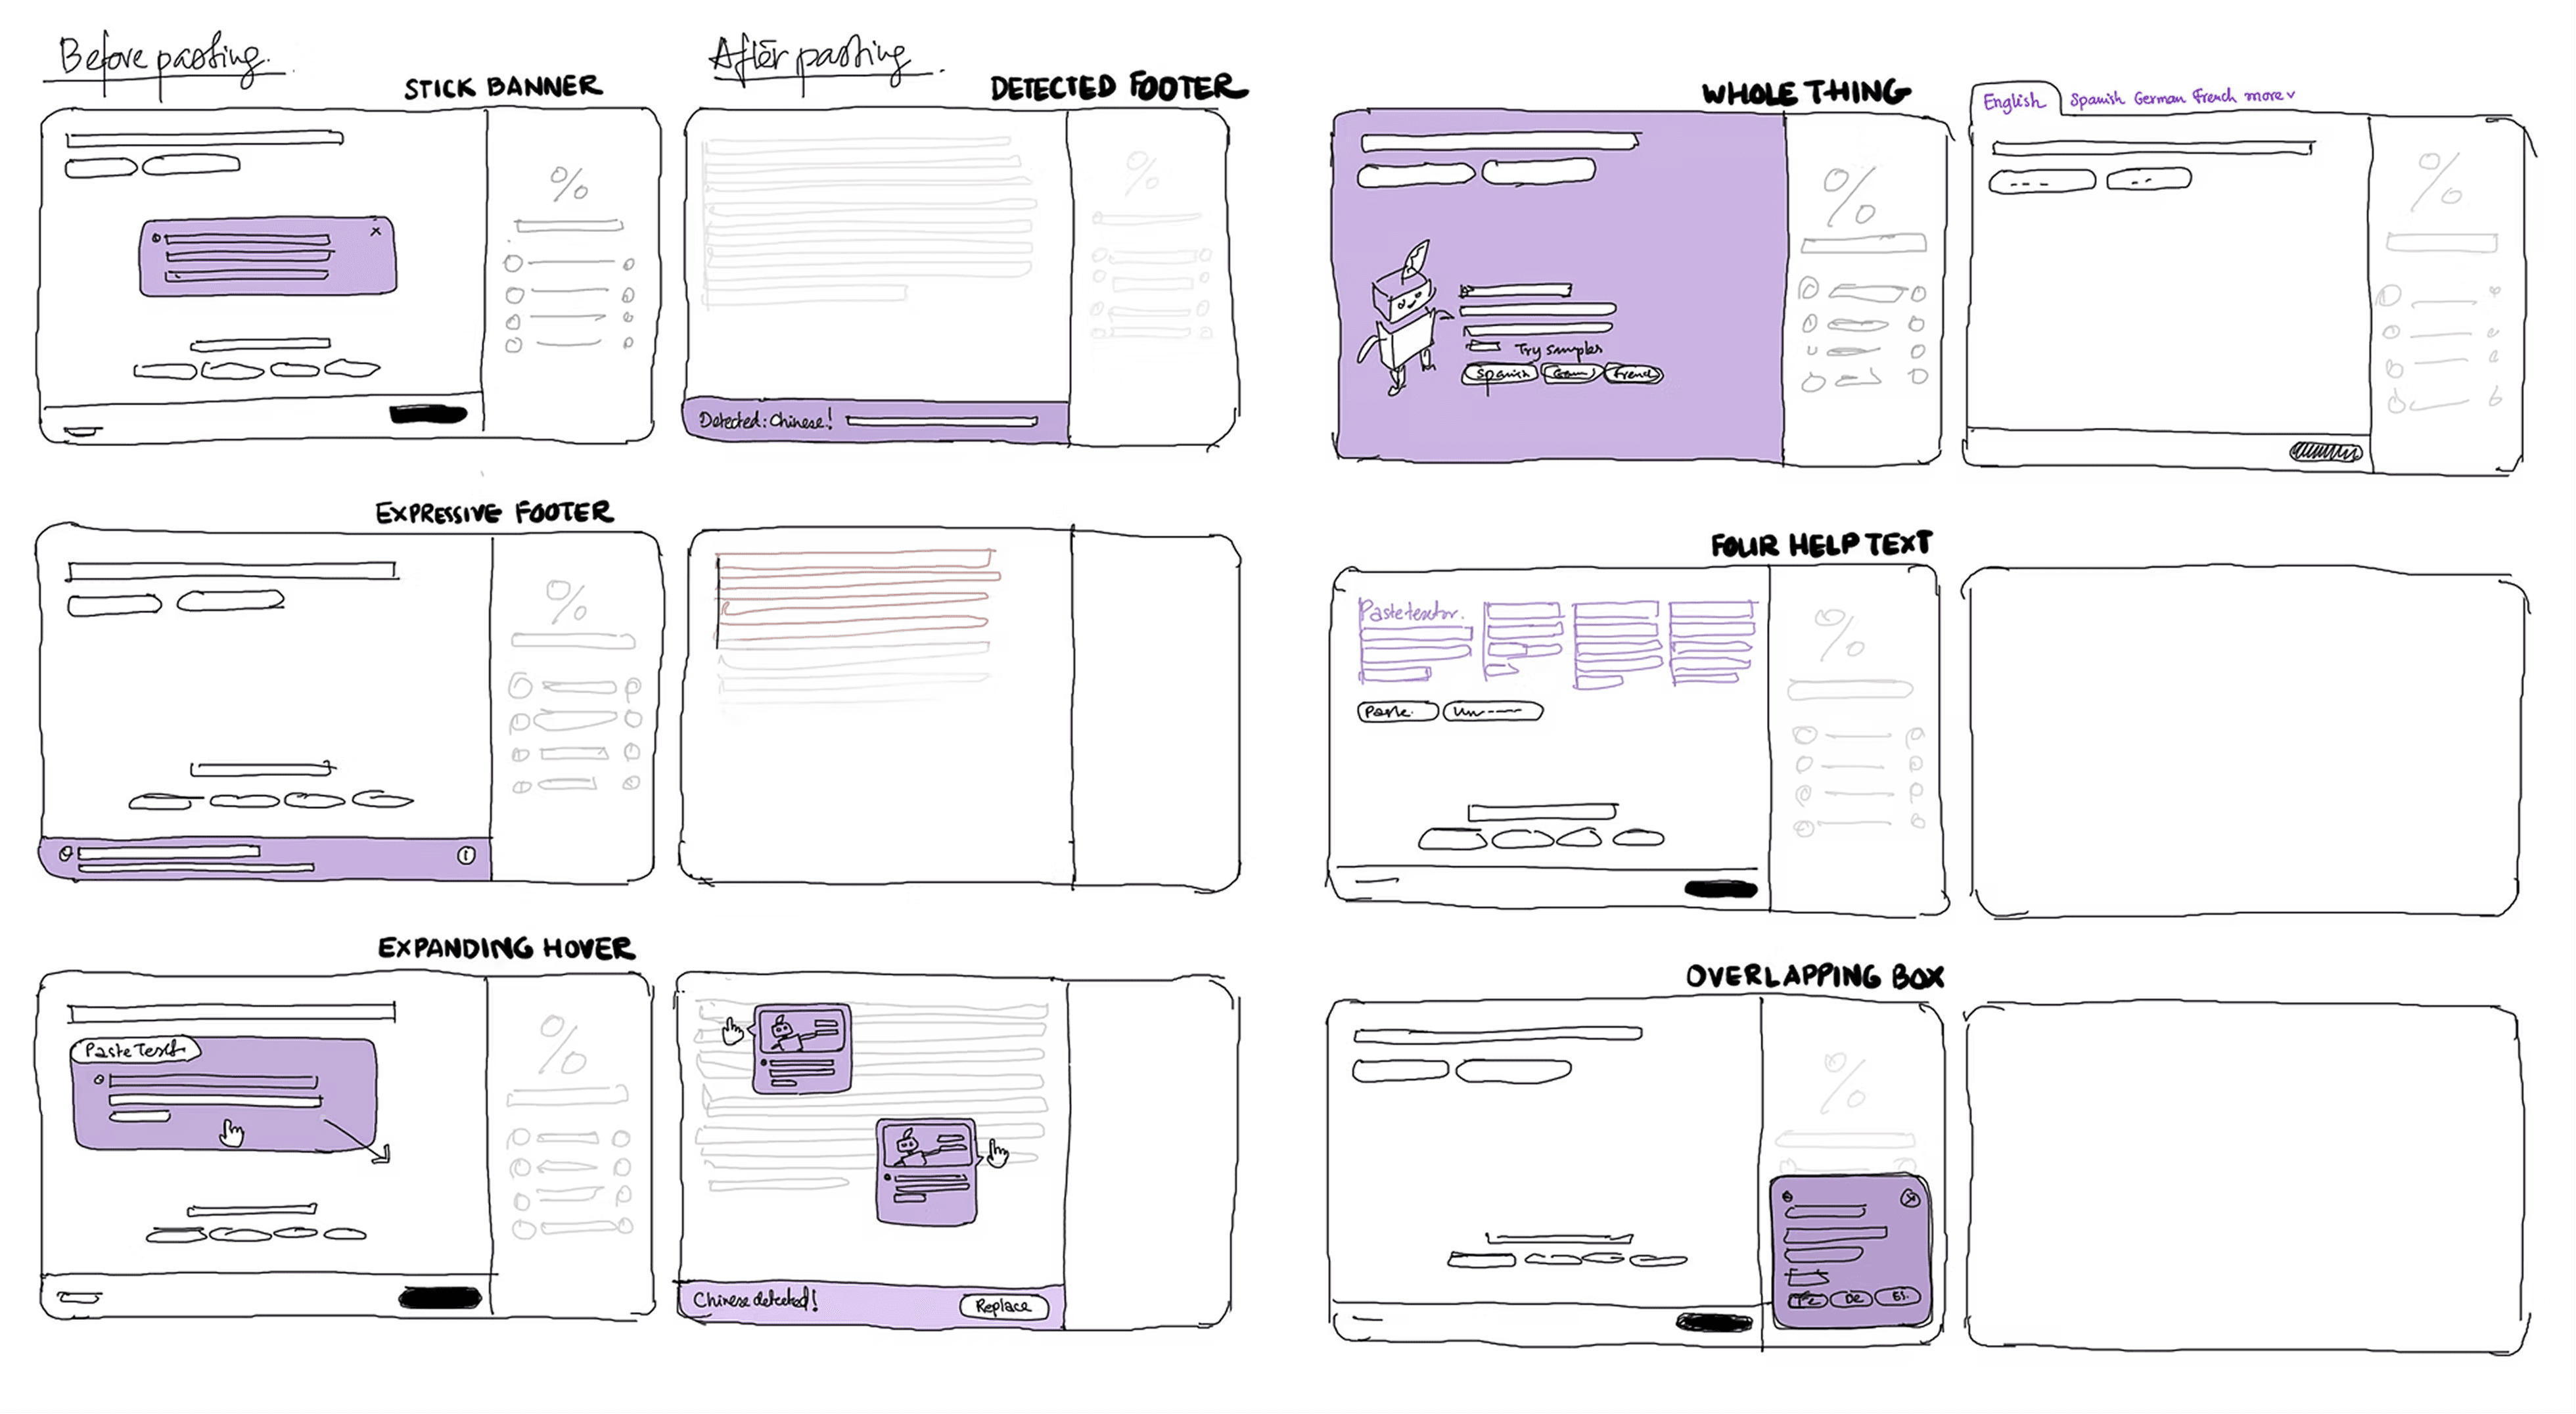
REJECTED · CROWDED

SELECTED · CLEANER

SEO signal
MVP
~100 WAU
Learned
V1
~300 WAU
Learned
V2
~500 WAU
WHAT SHIPPED IN V2 · 22nd FEB 2024
We adjusted our course based on observed user behaviour.
The whole approach was no less than a participatory design method, where constant feedback & data took our thinking one step closer to the user needs each time.
INTERVENTION
PRIMARY JOB
DELIVERY
All in MVP
Primary action
MVP
Icon to side nav
Discovery
SHIPPED V1
Score clarity
Trust-worthiness
SHIPPED V1
4-way classification
Score explanation
SHIPPED V1
Sentence highlights
Add specificity
SHIPPED V1
Manual edits
Continuity & control
SHIPPED V1
Conservative model
Accuracy
SHIPPED V2
Like Dislike
Model feedback
SHIPPED V2
Soft verdict
Expectation setting
SHIPPED V2
Cross-sell portfolio
Address next action
SHIPPED V2
Sample text
Tool education
SHIPPED V2
Multi-language
Business objective
SHIPPED V2
Report download
Produce evidence
NEXT
Premium gate
Monetisation
LATER
Reason why AI
User value
LATER
Scale to more languages
Business objective
LATER
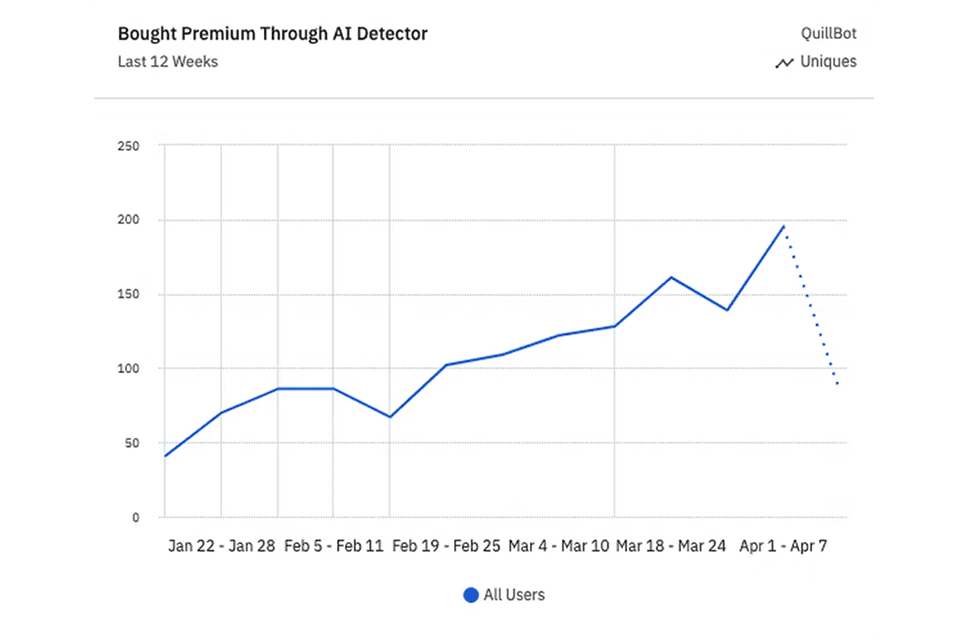
Traction was real. So was the work went behind achieving the numbers.
The initial data validated rapid acquisition through the MVP, while feedback patterns exposed where the product needed immediate calibration.
500K
#2
#200
90%
BASELINE MVP
~100 WAU
Immediately on launching AI Detector MVP, we witnessed 100K WAU.
V1 · WEEK 5
The version 1 aimed at product coherence while optimising it for user feedback & business goals.
V2 · WEEK 7
Primarily resolved false positives.
Aimed at implementing new learnings from version 1, it primarily reduced false positives.
OBSERVED ON WEEK 12
~500 WAU
The tool proved itself a loss-leader by letting ~2M MAU to user with a conversion rate of 0.04%.

AI-Human interaction design is part of the product’s integrity.
What I would do differently?
Use conservative model since inception and better expectation management to uphold trust.
What this changed in my practice?
